Showing posts with label Data Governance. Show all posts

Wednesday, August 3, 2022

A Future-Oriented Approach

Enterprises take on a wide range of projects in the name of “Digital Transformation”. Or seek to set up programs for Data Governance, Master Data Management, Data Catalog, Business Glossary, Data Protection, Data Strategy, etc.

However, legacy systems and technical debt continue to impede many organizations' efforts. And any attempt to use such a burdened environment as a launchpad for future-proof “data” projects and programs is most likely doomed to fail.

Recommendation

The future of informational infrastructure needs to be based on a business-data-driven reference system with well-defined, distinct responsibilities. Prerequisites are

Here is the industry-agnostic approach that I propose:

  1. For each business unit, record the major organizational processing activities
  2. For each processing activity, record the major created & updated (business) data structures
  3. With recorded data structures, derive (business data) entities & relationships
  4. With entities & relationships, build the Enterprise Information Management Map (= high-level concept model)

  5. Example of High-Level Concept Model in Liability Insurance [Click to Enlarge]

  6. In the Enterprise Information Management Map, identify master entities and the relationships among them
  7. In the Enterprise Information Management Map, assign responsibility for modeling master entities & relationships to Chief Data Office(r) as their Data Domain Owner.
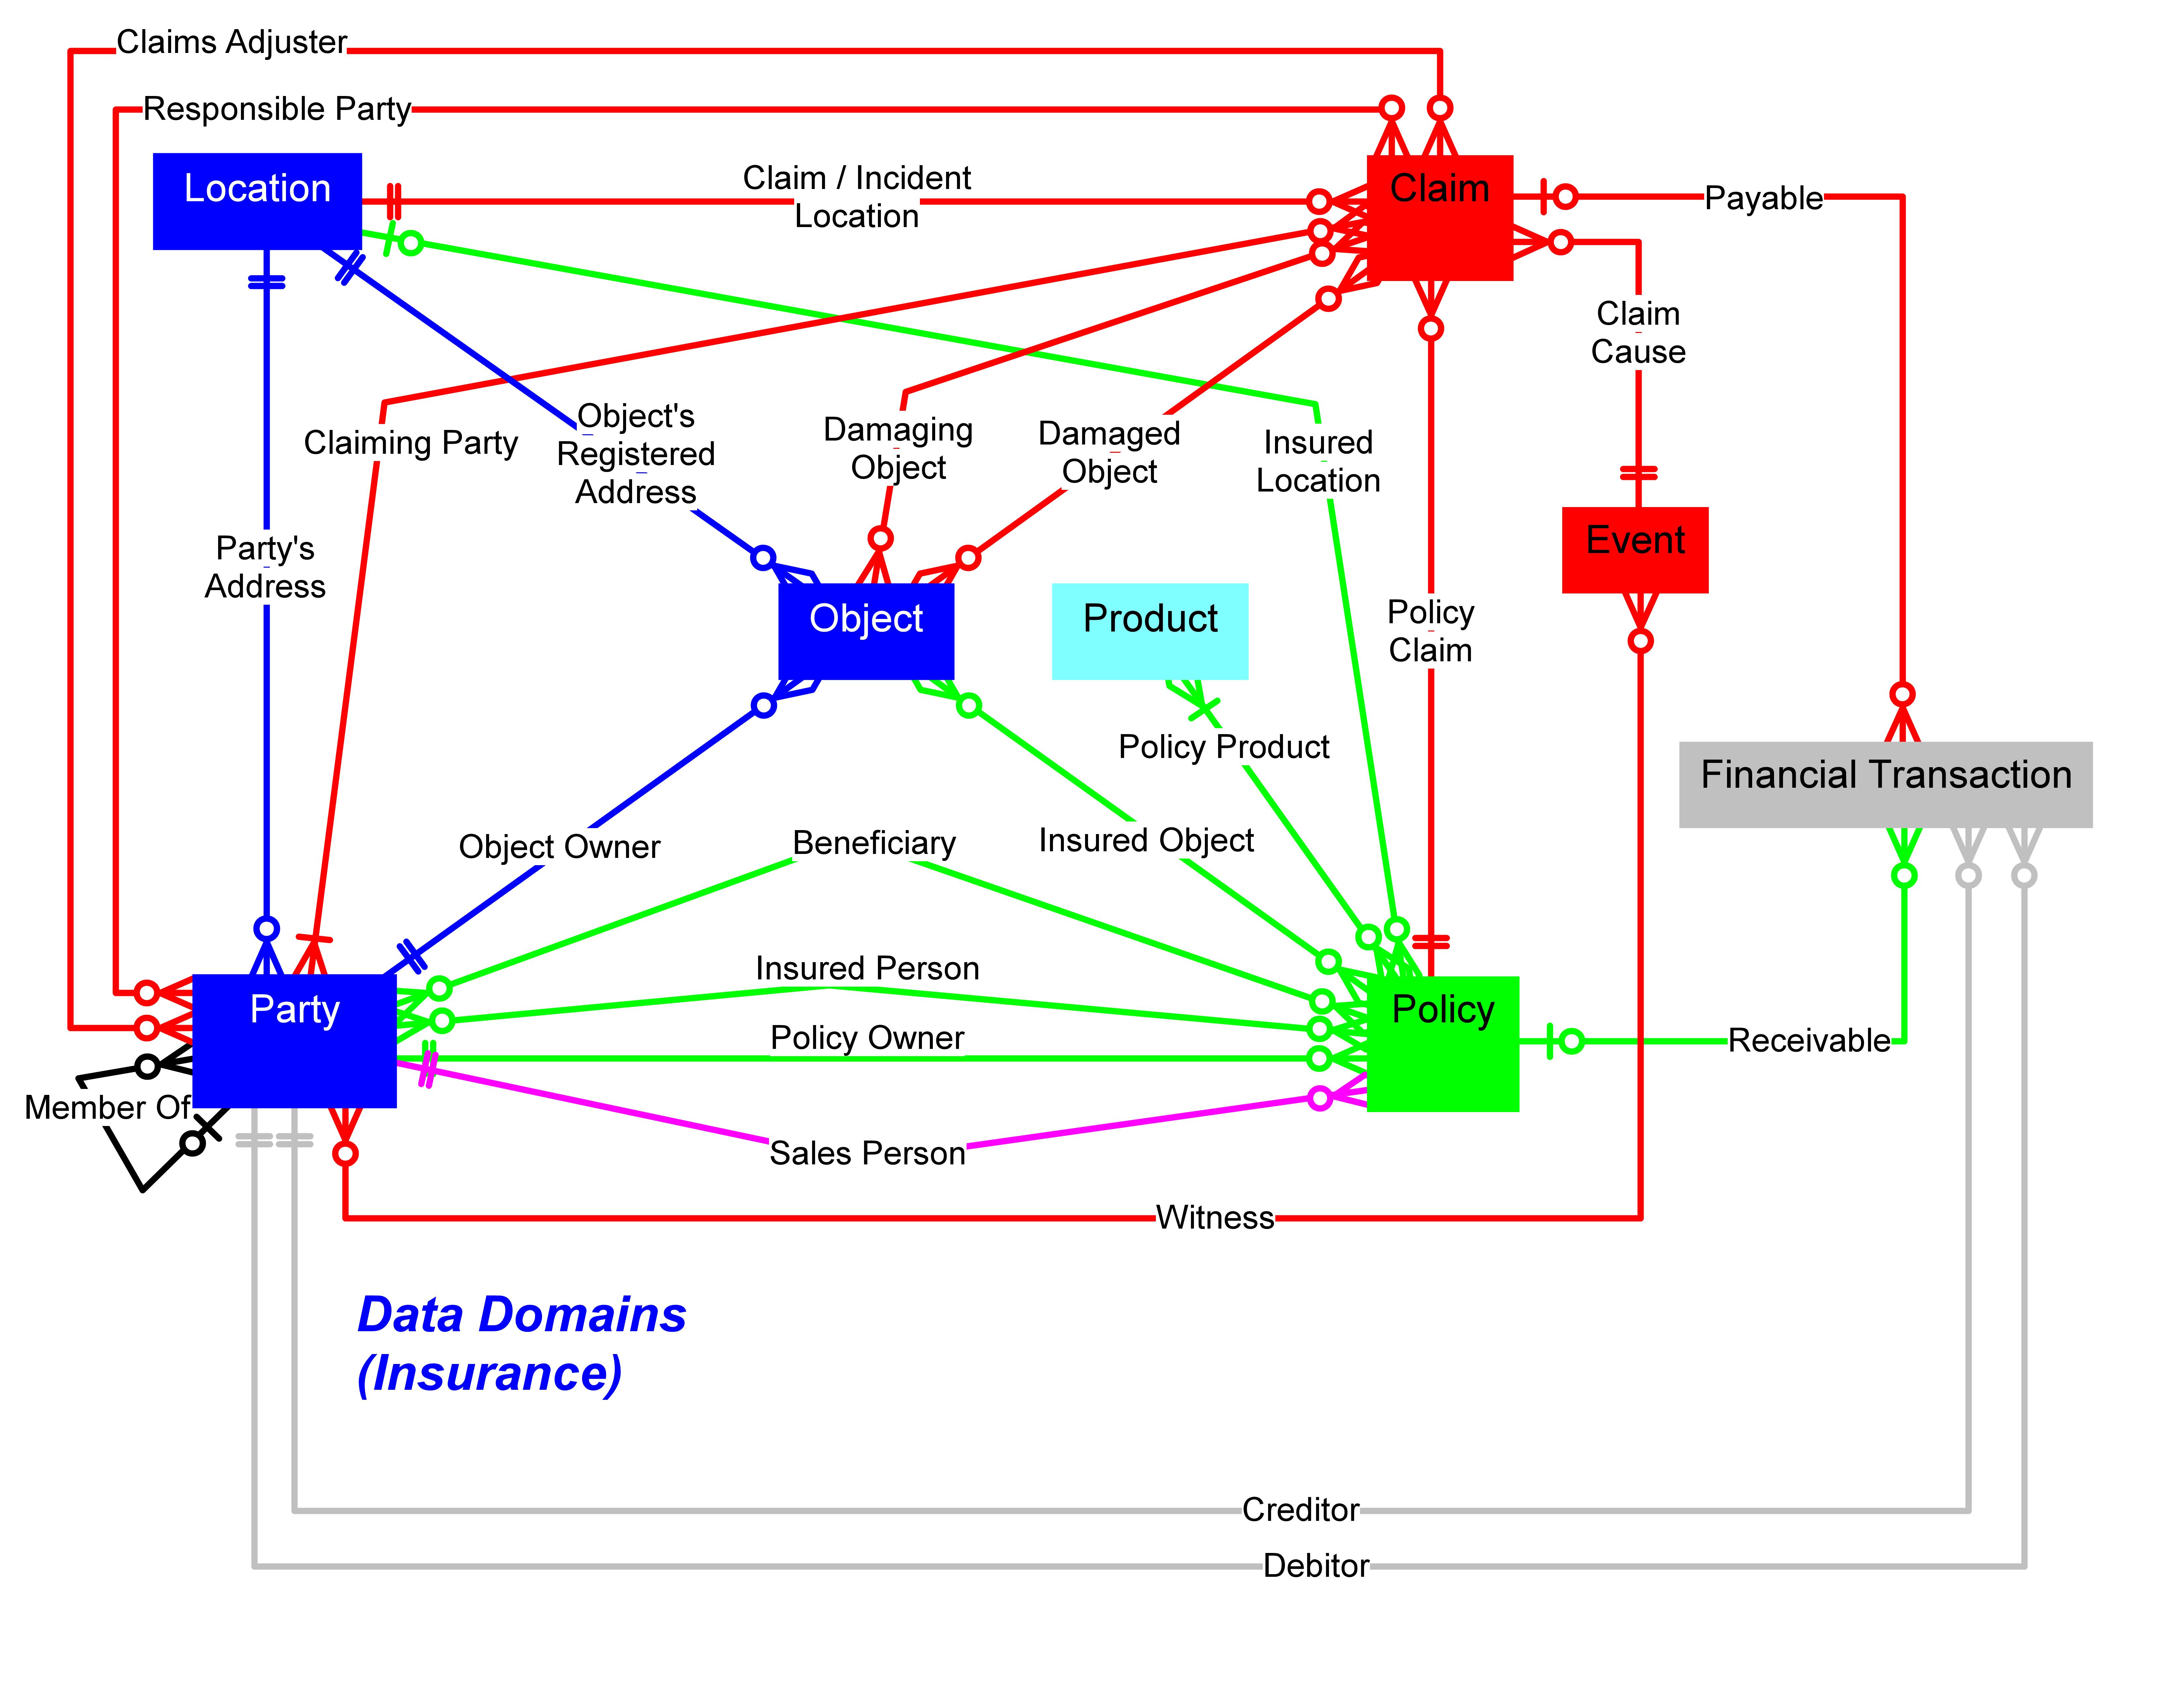
  8. Divide the Enterprise Information Management Map by grouping all other entities & relationships into distinct data domains based on similar processing activities and assign modeling responsibility for each data domain (= Data Domain Ownership) to exactly one business division [Note: If necessary, restructure processing activities in a way that each data domain and its creating / updating processing activities belong to only one responsible business division.]
Example of Data Domains in Liability Insurance [Click to Enlarge]

Result

The above approach introduces a reference structure where each data domain within the enterprise concept model is represented by exactly one business division that is responsible to develop & maintain the related business data names, descriptions and constraints for business entities, attributes and relationships.

Outlook

In subsequent posts I will elaborate on this frame to show how to advance enterprise-beneficial data programs and projects.

Sunday, January 16, 2022

Risk Management

Organizations are exposed to business risks in varying degrees. These risks can be categorized as:
  • Operational / strategic risk, which includes anything that could impede the organization's performance due to
    • external events (e.g. pandemics, natural catastrophes, climate change)
    • internal events (e.g. labor issues, strike)
    • technology problems (e.g. increasing technical debt)
    • vendor choice / turnover
    • security issues (e.g. CyberSecurity)
  • Reputational risk, which summarizes potential harm to the organization's
    • internal perception by its employees and shareholders
    • external perception by customers and the general public
  • Compliance risk, which is related to the organization's responsibilities under applicable laws and regulations
  • Environmental, Social and Governance (ESG) risk, which pertains to the organization's business ethics and practices (e.g. environmental management, respect for human rights, anti-bribery/-corruption, financial reporting)
Since risks often affect multiple business units or the whole organization, it is important to centralize risk management, i.e. the responsibility for identifying, assessing and mitigating threats that may significantly impact the organization in its ability to conduct its current and future business. Particular attention needs to be paid to cumulative risks, i.e. the organization’s total exposure that amounts from the existence of several parallel, but independent risk factors with the same impact (e.g. several vendors that process personal data on behalf of a certain organization could independently suffer a data breach).
 
Risk management is typically headed by a corporate executive, the Chief Risk Officer (CRO). Small and medium sized organization may not establish a separate position for risk management, but assign the related responsibility to another executive (for the sake of simplicity, hereinafter also called “CRO”). The CRO should ideally report to the CEO or the Board. As most of the risks have a financial impact, the CRO may instead report to the Chief Financial Officer (CFO).
 
Having a horizontal responsibility (such as the CFO, Chief Human Resources Officer (CHRO), or Chief Data Officer (CDO)), the CRO needs to be an excellent communicator and influencer.
 
The CRO’s responsibility includes the following tasks of risk management:
  • Document process maps with focus on risk to both information and material, both in transfer and in rest
  • Analyze the organization’s risk profile in terms of potential operational, strategic, reputational, compliance and ESG risks
  • Identify risk factors that could have the same impact 
  • Determine and quantify the organization's risk appetite
  • Develop action plans to mitigate risks to the organization – both strategic and tactical
  • Seek insurance coverage for remaining risks 
  • Integrate risk management priorities into the organization's overall strategy
  • Plan and oversee budget for risk management and related projects 
  • Monitor the progress of risk mitigation efforts
  • Communicate risk analysis and mitigation progress to the organization’s executives, board members and heads of business units

Sunday, September 26, 2021

Managing Business-Driven Data Models

In my previous post "Managing Data Models" I emphasized the Logical Enterprise Model as the center piece of model management.

Since the Logical Enterprise Model builds over time, a CDO suggested to me that she would like to integrate a “Corporate Map” into the model management process. This map would be developed in moderated sessions with C-suite members to provide guidance to corporate leaders and stakeholders how business areas are related, which Data Strategy to choose and which projects to prioritize. 

Our conversation brought us quickly to what I introduced as an “Enterprise Information Management Map” in my past posts using an example for the insurance industry:
 
 
Enterprise Information Management Map

Click to enlarge

 
Adding the development of an Enterprise Information Management Map to the model management process for a more business-driven top-down approach:
 
Business-Driven Data Model Management

Click to enlarge


Wednesday, September 8, 2021

Managing Data Models


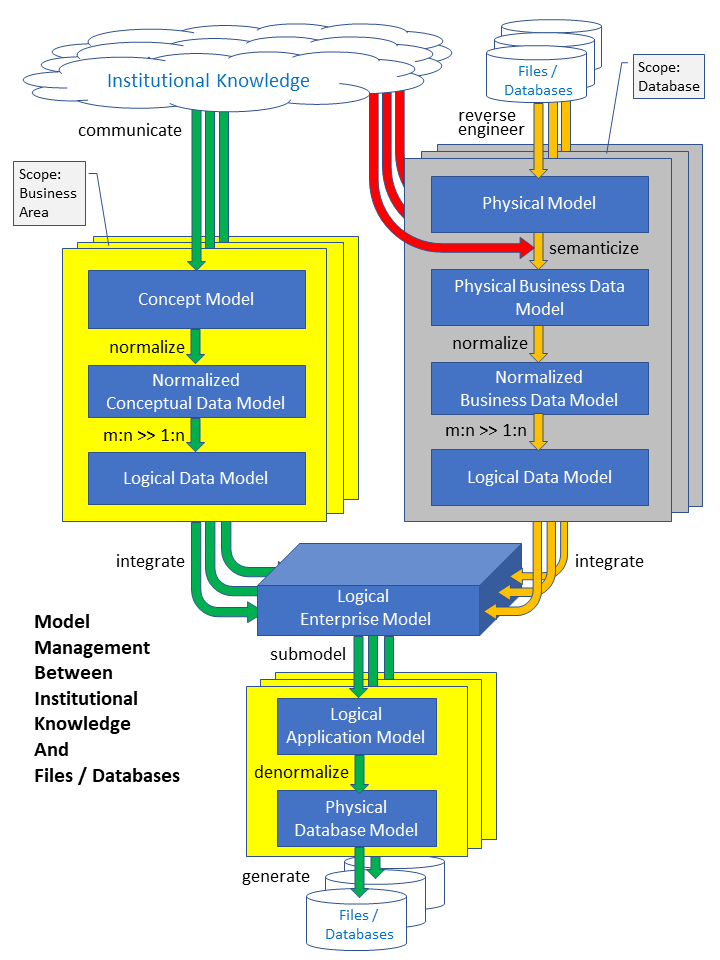
A functioning data modeling environment could look like this:
 
 
Too complex? Not if you consider that most organizations need to maintain legacy systems in parallel to developing new applications – and both in a flexible or even agile manner.
 
Though delimitations between model levels may vary among readers, this image suggests the principle steps and resulting artifacts to proceed from institutional knowledge in  business departments to structures of files and databases.
 
While I may revisit this approach in future discussions and explanations, I will restrict myself here to a few key comments prioritized by recent discussions with clients.
 
1. First and foremost, using a structure like this effectively and efficiently obviously necessitates a professional tool set of well connected components. (Though I am biased* regarding the choice of tools, the approach outlined here should not impose a particular technical solution.)
 
2. In overcoming departmental silos, the Logical Enterprise Model plays a central role connecting business attributes with potentially multiple physical occurrences in different application systems and databases (Data Catalog). As opposed to the (failing) approach of creating a “complete” enterprise data model first, I suggest to build the Logical Enterprise Model by integrating partial Logical Data Models from ongoing business projects. Due to its central role, this integration process and the maintenance of that model needs to be assigned to a central BUSINESS unit, e.g. the Chief Data Office. Since naming and definitions are a mandatory part of business data modeling, a Business Glossary is an implicit component of the Logical Enterprise Model. 
 
3. It is not uncommon that organizations operate production databases which were developed in another (incompatible) project environment 20 or more years ago, i.e. those legacy databases may be insufficiently documented and/or the last knowledgeable programmer / database administrator has meanwhile left the organization. To simply shut down those databases may not on be an option, if they still support valuable business processes, at least not without first migrating the enclosed data to a new storage system. Both maintaining or migrating a database require to know its structure (tables, columns, keys, etc.). Fortunately, professional data modeling tools support “reverse engineering”, i.e. they can recreate the physical data model usually directly from a database.
 
However, the reverse engineering process may leave expectant users with frustration as cryptic, abbreviated physical names in databases are common and do not reveal the semantics necessary to understand and document the purpose of tables and columns. Also, the sheer number of tables can be overwhelming.
 
The best strategy “forward” to identify the relevant submodel (“Physical Business Data Model”) is to find the meaning of core tables (i.e. tables that have multiple relationships) and from the subset of interest to navigate to neighboring objects.
 
The necessary business semantics to enrich the model with logical names and definitions can be obtained
  • as part of the reverse engineering process if the developers of the database used in-line documentation features (as e.g. supported by Oracle or SQL Server).
  • from database-external sources (e.g. ERP systems often hold the necessary business information in a separate dictionary).
In absence of these tool-supported options, the reverse engineering approach is limited to tap some business users' knowledge to semanticize the reversed model. While this can be a tedious process including trial and error, it is inevitable to do it, if neither shutting down the database nor continuing to operate it as-is are viable options. Legal obligations (e.g. to comply with applicable data privacy laws) may cause additional pressure to follow this inconvenient, but necessary path to reduce technical debt.
 
I welcome your questions and comments.
 
[* In the spirit of full disclosure: I represent Grandite, the supplier of the SILVERRUN Business Architecture Tools]
 

Sunday, December 15, 2019

A Privacy Regulation Applying in the USA and Canada (and Everywhere)

Although the General Data Protection Regulation (GDPR)* was passed more than three years ago and entered force more than one year ago, there is still confusion and misconception about the regulation’s sphere of impact.

In a new series of posts, I will share some advice** drawn from experience in projects that I have conducted since the inception of the regulation, but also include updated guidelines that the European Data Protection Board (EDPB) recently published*** regarding the regulation’s territorial scope (Art.3 GDPR). To avoid amendments and editorial notes to my original post under this subject, I offer below a complete rewrite.

Although I encourage everyone to read the provisions of the GDPR as well as the above mentioned EDPB guidelines (which illustrate typical cases by example), here are the major takeaways regarding the GDPR's territorial scope:
  • GDPR is a regulation to protect personal data of individuals ("data subjects") who are physically present – and may it only be temporarily - in the EEA (European Economic Area – which includes all EU member states plus Iceland, Liechtenstein and Norway). Data subjects’ protection rights are not dependent on their citizenship or residency.
  • All organizations worldwide whose activities "intentionally, rather than inadvertently or incidentally, target" individuals being in the EEA are obligated to comply with the GDPR.
  • Organizations established in the EEA have additional obligations: They must comply with GDPR regardless of where in the world data subjects are located.

The following matrix shows under which conditions GDPR applies:
However, in a world of international trade and high mobility of individuals, organizations can obviously not control the data subjects’ whereabouts while a business transaction takes place or thereafter. (Even data subjects’ IP addresses captured during electronic communications do not prove presence in or absence from a certain territory since individuals can legitimately – and will increasingly – hide their real geographical location by employing Virtual Private Networks.) Therefore, I recommend that organizations as of row B conduct all their activities related to processing personal data in a GDPR-compliant manner.

From a practical perspective, the above matrix can then be simplified as follows:
In conclusion, any organization offering products or services worldwide must presume, by default, that GDPR applies to them. On the complementary, non-EEA businesses whose commercial target area is outside of the EEA will be exempt from GDPR compliance.
 
* Published at https://eur-lex.europa.eu/legal-content/EN/TXT/?qid=1528874672298&uri=CELEX%3A32016R0679
** Legal disclaimer: This blog post is not intended to be legal advice, but to raise awareness that it is recommended to consult a lawyer.
*** Published at https://edpb.europa.eu/sites/edpb/files/files/file1/edpb_guidelines_3_2018_territorial_scope_after_public_consultation_en.pdf


Thursday, October 3, 2019

How The GDPR Can Propel An Organization's Informational Infrastructure

I concluded a previous post "GDPR - More Than Just Another Regulation" stating that the GDPR (General Data Protection Regulation) forces organizations to prioritize a long-due overhaul of their informational infrastructure. 

In my understanding, a contemporary informational infrastructure is a system of people, processes and tools (software, hardware) that covers the five business disciplines represented in the image below whereas each level builds on the lower one(s).

Due to my observations, a vast number of organizations find themselves in the status where upper management hopes to advance level 4 and 5 to get the edge over the competition while business departments still struggle with the quality of level 3 due to a lack of foundation in level 1 and 2.

How does that relate to an organization's capability to comply with the GDPR? 

The sole purpose of the GDPR is the protection of an individual's rights as the owner of their personal data. However, since personal data are at the core of almost any business and even any business transaction, the GDPR's provisions imply a certain informational infrastructure. 

For example, GDPR grants any individual being in the EU ("data subject") a far-reaching control over their personal data records throughout the complete data life cycle with an organization, i.e. control over Create, Read, Update and Delete of their personal data (as long as it does not restrict the legitimate rights, liberties or legal obligations of other parties). 
  • Create: The creation of records requires the data subject's explicit consent or is necessary to perform a contract with the data subject [Art. 6 et al.]. 
  • Read: The data subject has the right at any time to know the total scope of captured and stored metadata and values related to their personal data [Art. 15 et al.] and to exclude usage of their data from certain purposes [Art. 21 et al.]. On the complementary, the organization has the obligation to restrict the access to personal data on a need-to-know basis.
  • Update: The data subject has the right to rectify [Art. 16] and/or to restrict processing of their personal data [Art. 18].
  • Delete: The data subject has the right "to be forgotten", i.e. their personal data to be deleted upon demand [Art. 17].

Although the provisions of the GDPR do not explicitly mention any infrastructural measures as of level 1 and 2, it is obvious that the organization can only comply with the rights of the data subject (and fulfill its own respective obligations), if the whereabouts of the data subject's personal data are completely transparent at any time, i.e. if the organization employs
  • a data model of the personal data (that shows all the references and physical storages of personal data throughout the organization) [prerequisite for rectification and deletion] 
  • a map that shows all the information flows of personal data (data flow diagram, process model) through the organization [prerequisite for information about the usage purposes and potential objection] 
  • a functioning Master Data Management system that maintains "golden" records of personal data (or at least keeps possibly multiple records in sync) [prerequisite for rectification and deletion] 
  • a functioning Data Governance system [prerequisite to comply with the GDPR in general] 

Organizations should welcome the GDPR as they will profit from these measures far beyond the purpose of complying with this regulation...

Note: This post has been updated from an earlier version written before the GDPR entered force.  

Wednesday, November 29, 2017

Value of a Data Management Office

Inspired by a LinkedIn discussion here, below I respond to the two initial questions that Dylan Jones (@DylanJonesUK) posed:

Question 1: What is the value of a data management office and why do we need one?

To state the obvious first: People with an "office job" exclusively process data (emails, telephone calls (audio data), electronic documents, paper documents, personal communication with co-workers etc.). Presuming that the employing organization is profitable, (in a simplified view) the total value of the data processed by those employees must be higher than the total of their salaries.

To see how other corporate assets are typically managed in an organization, let's look at Finances (summarizing everything that is included in a balance sheet) and People. They find their organizational representation in departments for Finance (usually headed by a CFO) and Human Resources (usually headed by a CHRO). Notwithstanding that any business department manages its particular financial targets / budgets as well as its employees, on the corporate level the departments Finance and Human Resources fulfill a central role which includes the following tasks (as mentioned in my post "Pondering on Data and CDO (Chief Data Officer)"):

"In their respective realm, Finance and Human Resources a.o.
  • Develop corporate target scenarios and related strategies
  • Ensure that the organization follows legal and regulatory obligations
  • Advise business departments regarding strategic and legal aspects
  • Perform tasks that are not assigned to the department level, but to the corporate level (e.g. declare taxes, report to regulatory authorities, compose the balance sheet, negotiate with the workers' union)
  • Provide standard templates / procedures that operational departments can / must apply (e.g. standardize expense reports)

Since any item of the above list is abstractly applicable to the resource Data, I suggest that medium and large enterprises implement a central unit headed by a CDO (Chief Data Officer) who directly reports to the CEO."

More precisely, applying the above to the resource Data, the central Data Management Office's tasks include e.g.
  • Develop a High-Level Enterprise Information Management Map (also see my post here)
  • Ensure that the organization follows worldwide-applicable regulations such as the GDPR (General Data Protection Regulation) and industry-specific regulations such as HIPAA, Solvency II, Basel III etc.
  • Derive measures that respond to international, national and corporate requirements of Data Governance and advise business areas accordingly
  • Develop a detailed data model for the intersection of business areas (Master Data)
  • Conceive standard interfaces for Master Data Management and related hubs
  • Build a corporate Business Data Dictionary

Question 2: What are the pros and cons of having a centralised DMO versus separate DMOs per business area?

Central and decentral Data Management Offices are not mutually exclusive, but should complement each other in a collaborative climate (following the principle "Decentralize as much as possible, centralize as much as necessary"). While the obligations of the central DMO are mentioned above, each business area ought to have its separate DMO with Subject Matter Experts / Data Stewards representing their realms and performing tasks such as:
  • Develop a business-area-specific data model that details the High-Level Enterprise Information Management Map
  • Contribute to the corporate Business Data Dictionary
  • Enforce the rules of Data Governance in their respective business areas


Saturday, October 14, 2017

Some Basic Recommendations for Data Quality

Inspired by the initiative of Prash Chandramohan (@mdmgeek) here, below please find some basic notes and recommendations for Data Quality.

1. Create a business data model while limiting its scope to data which
  • You are legally entitled to collect
  • Have a clear business purpose
  • Have a purpose that you can explain to the respective target group (customers, employees, suppliers etc.)
while avoiding to re-create entities / attributes that are rightfully already defined within the organization.

2. Define all business metadata regarding
  • Their (business) meaning
  • Format (length, data type)
  • Nullability
  • Range of values (where meaningful and possible).

3. Define use cases and related rules that serve a purpose-specific data quality.

4. As much as meaningful / possible: In business processes, programmatically
  • Enforce the rules for business data (quality)
  • At least, suggest a use-case-specific selection of values.

5. Educate business staff according to their role and responsibility in business processes about the purpose / use cases of data, in particular about the impact of
  • Their choice of values when creating or updating data
  • Deleting data.

6. Monitor the quality of data on a regular basis while applying / interpreting (use-case-specific) rules, e.g. using the Friday Afternoon Measurement (even if it's not Friday!).

7. Provide feedback to business staff and / or business analysts.


Sunday, August 20, 2017

GDPR & Personal Data - Context is Key and (Foreign) Key is Context

A logical data model is one of the important milestones on the road to GDPR (General Data Protection Regulation) compliance. Being the blueprint of an organization's semantic data and the relationships among them, the logical data model serves as the virtual hub between the existing physical data stores and the future implementation of a GDPR-compliant data architecture.

The logical data model even offers a GDPR-related bonus, as it teaches that being 'personal' (or non-'personal') is not an absolute characteristic of data, but depends on the context in which these data are made available.

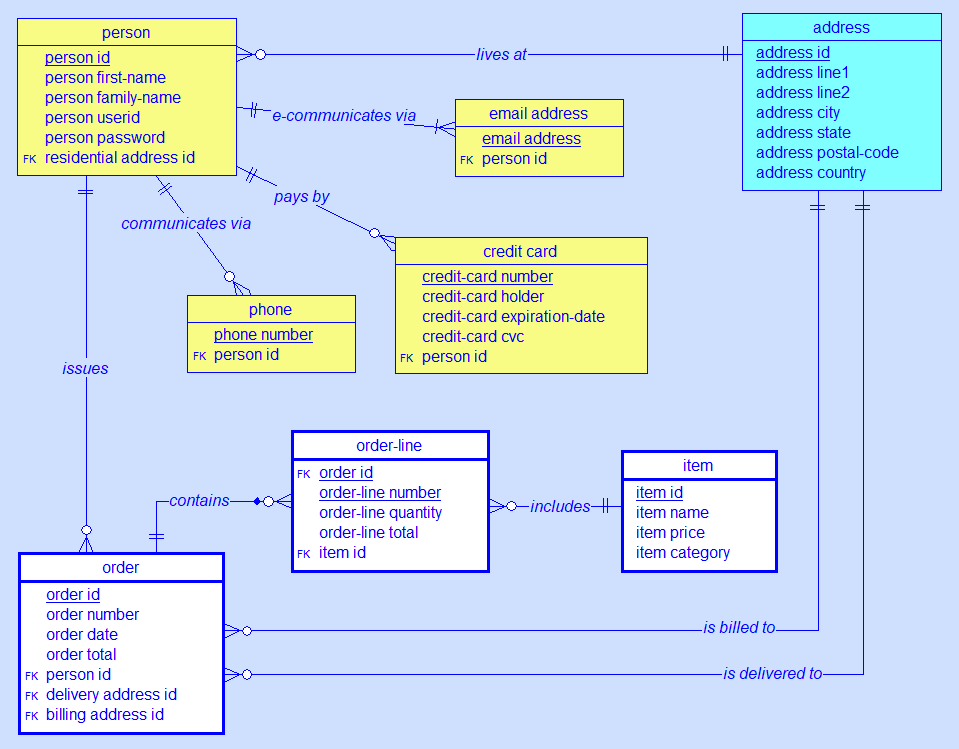
To illustrate the latter, let's look at an example of a logical data model which presumably represents the business of a B2C online retailer. This model may have been obtained as the result of the process described in my previous post "GDPR - How to Discover and Document Personal Data" or through any other modeling approach.

Click to enlarge

Which of these tables contain records with personal data?  As per the definition of 'personal data' imposed by the GDPR ('personal data' means any information relating to an identified or identifiable natural person), the answer is: All of them! 

Why? Because all tables are 'related' to the table 'person', i.e. there is a path from each table to 'person' (and vice versa).

This does not mean that all records of all tables shown here contain personal data, but those records that can be reached through a chain of foreign-key-value to primary-key-value links (or vice versa) from a 'person id' or to a 'person id'.

In other words, the existence of relationships (foreign keys) provides the context that categorizes records of data as 'personal' or 'non-personal'. For example, if we isolate the table 'address', its content simply constitutes a list of addresses which may exist in public reference databases such as Google Maps and therefore cannot be considered to contain personal data. But in the context shown in the above model, those records of the table 'address' that are identified by the value of the foreign key 'residential address id' in table 'person' (or by values of the foreign keys 'delivery address id' and 'billing address id' in table 'order') become personal data.

Still, the necessity and degree to protect personal data may vary from table to table and from column to column. The sensitivity of personal data must be evaluated, and the risk of processing personal data with respect to the rights and freedoms of natural persons must be assessed. Sensitivity and processing risk for each personal data element in isolation, but more importantly for their combination and in context will influence the physical design of data stores including measures of encrypting, pseudonymizing and anonymizing personal data to achieve GDPR compliance. But that will be subject to another post...

Wednesday, August 16, 2017

GDPR - How to Discover and Document Personal Data

One of the first steps for organizations on the journey to GDPR compliance is to find out what 'personal data' (i.e. any information relating to an identified or identifiable natural person) are stored where. For many organizations, this can be a tedious, cumbersome process, since very often the complete 'list' of all metadata describing personal data is not at hand right from the start. Making matters more complex, personal data's metadata (like any metadata) may be found under a variety of synonyms in different data stores. 

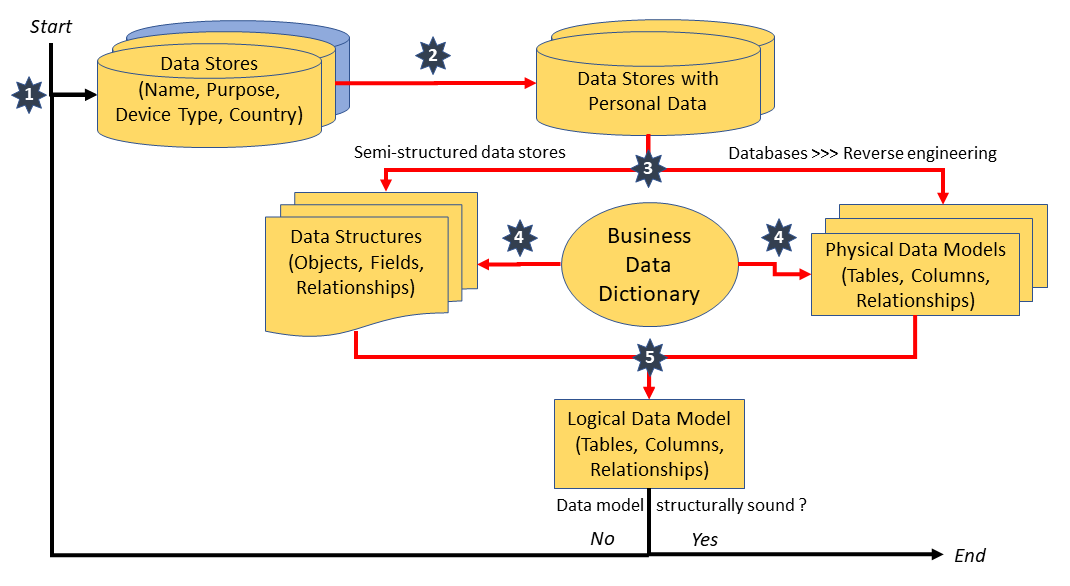
To streamline the process for data discovery as much as possible, I suggest a sequence of 5 steps which may need to be repeated several times. With each pass, additional personal data and/or their locations may be discovered based on the names of columns / fields added in a previous iteration. The process can be stopped once a consolidated, structurally sound logical data model has been obtained. 

Click to enlarge
The steps include:
  1. Create an inventory of all data stores. Record their name, purpose and  physical location (device type, country!). Important: Include locations where potential 'processors' (contractors) store business data on behalf of the 'controlling' organization! 
  2. Select (subset of) data stores that are already known to contain personal data. (In a first iteration, start searching data stores using typical metadata of personal data! In later iterations, search data stores using additional metadata of personal data based on the logical data model previously created (see step 5).) 
  3. Capture / reverse engineer the physical model of the selected data stores.
  4. For each selected data store, identify metadata (field names) of personal data and of objects relating to personal data. Assign business meaning to those fields by linking them to semantic items from your business data dictionary. (If you do not have a business data dictionary, create one in parallel by using existing documentation and involving subject matter experts!) 
  5. Create / enrich (partial) logical data model using the business data dictionary.
Although this is only the beginning of the journey, professional data (and process) modeling tools are obviously necessary on the road to GDPR compliance. (Note: All red arrows in the above image do not only indicate step sequence, but ought to also represent links among the related artifacts in the modeling tools' metadata repository.) Having already a business data dictionary in place and/or logical and physical data models tool-documented will greatly facilitate the process.

Stay tuned and read part 2 "GDPR & Personal Data - Context is Key and (Foreign) Key is Context" where I will demonstrate how context is important to determine whether data are to be considered personal or not with respect to the GDPR.

Sunday, June 4, 2017

GDPR Necessitates a Professional Data Modeling Tool

In his recent article Data governance initiatives get more reliant on data lineage info, David Loshin pointed out that "data lineage management offers a compelling scenario for improving the data governance process". Loshin distinguishes two aspects to Data Lineage, one structural and the other related to data flows which I characterize as follows:
  • Structural Data Lineage - mapping and tracking semantic data objects (and their synonyms) throughout the organization from elements of conceptual and logical schemas to their physical occurrences in databases
  • Dynamic Data Lineage - mapping and tracking the flow of semantic data objects (and their synonyms) from their sources, through the processes and data stores of the organization to downstream consumers.

In my post How The GDPR Can Propel An Organization's Informational Infrastructure I mentioned that recording Data Lineage is implicitly required by multiple regulations, most prominently the General Data Protection Regulation (GDPR).

Let's bring this to life using an example scenario of the not so distant future:

Thomas, an EU resident, is client of the online retailer xyzAnywhere Corp. which communicates with Thomas usually by email, but occasionally chooses to send him promotional letters by post mail. Thomas receives some of xyzAnywhere's promotional mail at his current residential address (as shown in his online profile), but also still some of their letters via mail forwarder as they are sent to his previous home. Thomas exercises his right granted by the GDPR to request a copy of the entire personal data that xyzAnywhere Corp. holds about him.

Upon receipt of that copy, Thomas realizes that the information provided to him does not include his previous residential address at all.

Regardless of how the communication between the customer and the organization may continue and leaving aside whether and how regulatory authorities will consider the case and penalize the organization, we can conclude that the organization failed to comply with GDPR (Art. 15), as it did not make the complete set of the customer's "personal data undergoing processing" available.

How could the organization have avoided to fail?

By employing a professional data modeling tool that especially
  • Features the creation of a business data dictionary where all semantic data objects can be uniquely named and well-defined for the entire organization
  • Supports to map and trace all synonym occurrences that may exist throughout the organization related to a data dictionary entry
  • Serves to represent a model of Master Entities and their physical distribution.

The data modeling tool SILVERRUN fully supports the above criteria and helps you to build a solid foundation for Data Model Management, Master Data Management and Data Governance.
 
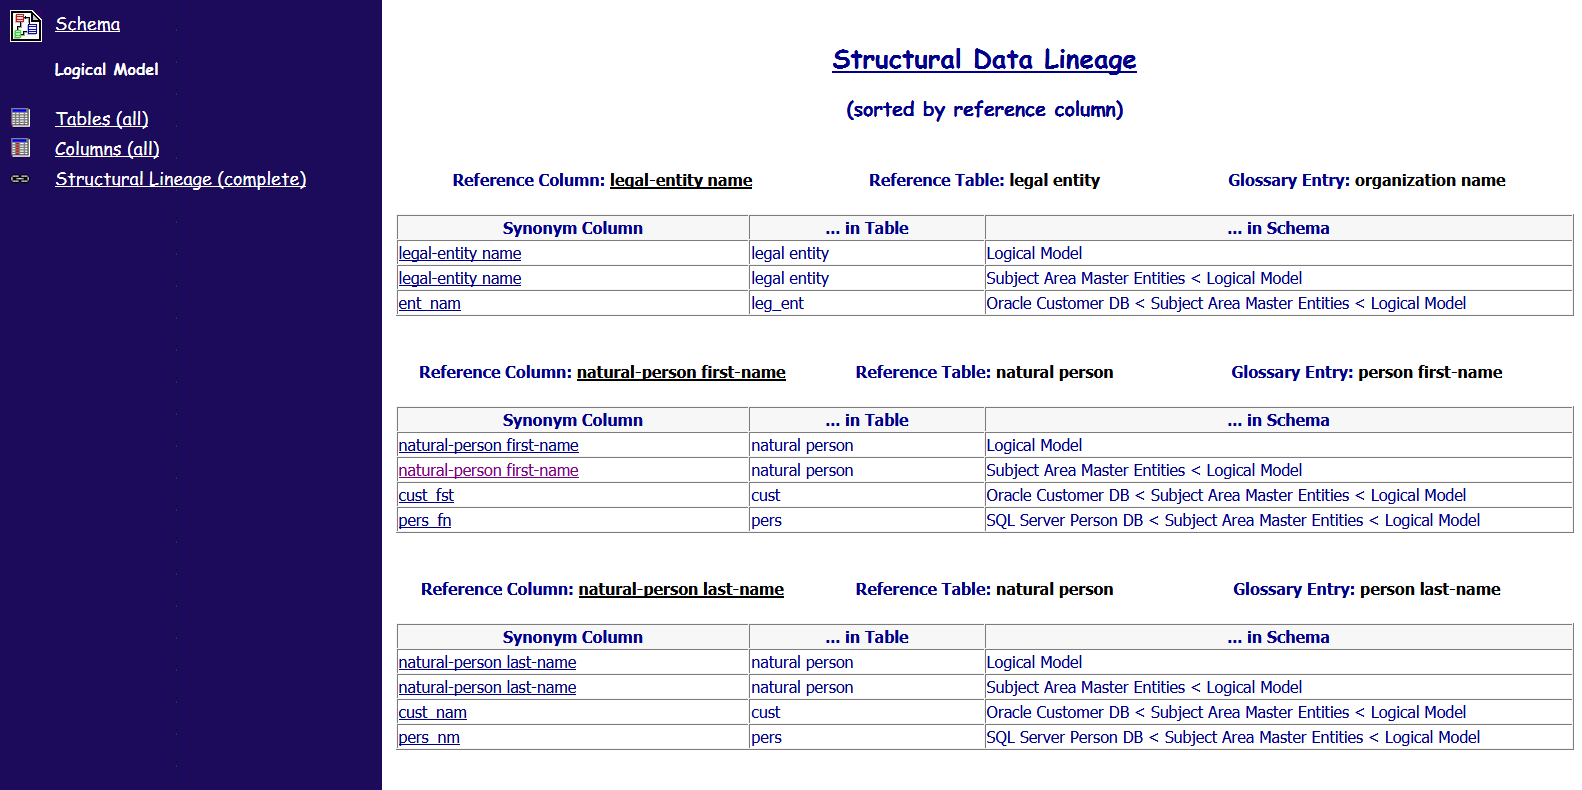
Below please see how SILVERRUN reports Structural Data Lineage which would have helped in the above example scenario to identify all database columns that constitute synonyms e.g. of the data dictionary item "person last-name" and thus define the data model needed to systematically extract all personal data related to a particular customer.
 
SILVERRUN RDM Relational Data Modeler - Tool for Conceptual, Logical and Physical Data Modeling
Click to enlarge


To be clear:  Links between a data dictionary item (glossary entry) and its synonyms can only be created by "brainware", not by software (alone) since the semantics behind any data object has to be understood first. However, with human guidance, SILVERRUN can integrate the puzzle pieces that may be available through reverse engineering of databases, importing spreadsheets, reusing existing models and accessing other sources of documentation. 

Once integrated, the resulting data model constitutes the solid ground to build a future-proof Master Data Management system and to flexibly respond to regulatory requirements as e.g. stipulated by the GDPR.

[In the spirit of full disclosure: I represent Grandite, the supplier of the SILVERRUN tools for data and process modeling.]

Monday, April 3, 2017

GDPR - More Than Just Another Regulation

It has become all too common that business initiatives targeting infrastructural improvements such as Enterprise Architecture & Business Modeling, Data Governance & Master Data Management, Privacy & Data Protection are put on the back-burner or are totally suppressed in favor of endeavors that promise monetary benefits in the short term.

Accordingly, few organizations are really prepared for a timely response to requirements imposed by law or by industry-specific regulatory authorities. Considering the usually moderate fines for non-compliance and potentially little other consequences, delayed reaction and acceptance of the risk to eventually be hit by the proverbial stick have become an element of business calculation.

When conceiving the General Data Protection Regulation (GDPR), the European Union (EU) obviously anticipated that a non-negligible number of organizations would be reluctant to comply rather than making reasonable efforts. EU lawmakers have therefore replaced the penalty stick with a sledgehammer right out of the gate (May 2018). In plain English, the EU's powerful message says: 

"If you, the organizations of the world, process personal data of our people, you have to respect the provisions of the GDPR, otherwise we will hold you accountable with fines of up to EUR 20 million, while in return we apply the same rules to our organizations when it comes to processing personal data of your people."

Not emphasizing nations or ideologies, but simply putting people first, is not only a strong political statement, but a directive that will change the way how business will be done in the foreseeable future. It is a contemporary way of saying "the customer is king" while forcing organizations to prioritize the long-due overhaul of their informational infrastructure. 

Too bad that we need lawmakers to remind us of what should have been common sense in the first place.

Tuesday, December 29, 2015

Pondering on Data and CDO (Chief Data Officer)

A successful approach to organizing a business is to avoid overhead, i.e. to decentralize responsibilities as much as possible and to centralize as little as necessary. Having this in mind, I closed an earlier post "Close encounters with the 3rd resource" postulating that business departments take their ownership and responsibility to govern Data as assets.

Since governing the other two main resources, Finance and Human Resources, as assets were established early on and practices are not widely disputed, it should be deemed worthwhile to explore how Finance and Human Resources are fostered in a balanced approach between centralization and decentralization:

In medium or large enterprises, Finance and Human Resources are typically represented by central organizational units, headed by the CFO (Chief Financial Officer) and the CHRO (Chief Human Resources Officer), respectively, each of them directly reporting to the CEO. In their respective realm, Finance and Human Resources a.o.
  • Develop corporate target scenarios and related strategies
  • Ensure that the organization follows legal and regulatory obligations
  • Advise business departments regarding strategic and legal aspects
  • Perform tasks that are not assigned to the department level, but to the corporate level (e.g. declare taxes, report to regulatory authorities, compose the balance sheet, negotiate with the workers' union)
  • Provide standard templates / procedures that operational departments can / must apply (e.g. standardize expense reports)

Any item of the above list is abstractly applicable to the resource Data, therefore, I suggest that medium and large enterprises implement a central unit headed by a CDO (Chief Data Officer) who directly reports to the CEO. 

More precisely, the Chief Data Office(r)'s tasks ought to include e.g.
  • Develop a High-Level Enterprise Information Management Map (also see my post here)
  • Ensure that the organization follows worldwide-applicable regulations such as the GDPR (General Data Protection Regulation) and industry-specific regulations such as HIPAA, Solvency II, Basel III etc.
  • Derive measures that respond to international, national and corporate requirements of Data Governance and advise business areas accordingly
  • Develop a detailed data model for the intersection of business areas (Master Data)
  • Conceive standard interfaces for Master Data Management and related hubs
  • Build a corporate Business Data Dictionary

Taking this approach, the enterprise will fulfill a crucial prerequisite to govern Data as an asset of the organization. 

Wednesday, October 14, 2015

Close Encounters With the 3rd Resource


No business can operate without people, at least it requires the person that manages and represents the business, the CEO. S/he will need funds (Finance) to run the organization, hire additional people (Human Resources), rent a place for the business etc. The organization will develop products/services, acquire clients and look for suppliers. The business will collect and record Data, i.e. pieces of information about its products / services, clients, addresses, orders etc.. The recording of Data contributes to the organization's long-term memory, to information that can be shared within the organization to function effectively and efficiently, which by definition makes Data a resource.

In fact, Human Resources, Finance and Data are the three essential business resources that any organization has always been built on, independent of its size or industry, regardless whether it operates locally or globally or whether its products / services are tangible or not. Moreover, in various business branches (e.g. banks, insurances, public administration) these are the only resources. (Herein, the term Finance is used to summarize all items which traditionally appear on balance sheets as assets or liabilities and thus describe the financial status of an organization, including e.g. cash, loans, real estate, machinery.)

The ultimate target of a business is to turn resources into assets which implies that resources are governed to increase revenue, to lower costs and to minimize risks, all in alignment with the organization's mission and goals as well as with the legal and regulatory requirements for the respective industry.

As the CEO is responsible to the Board to accomplish the business targets, s/he may want to especially ensure that managers at the senior level (VPs) contribute their share to the set out goals and advise their subordinate management levels to govern the resources accordingly. However, to be successful, such top-down leadership also requires that the hierarchical structure remains horizontally cohesive, i.e. departments on the senior management level do not develop as independent organizational, cultural, informational or technical resource silos.

While governing Finance and Human Resources as assets had been established early on, senior-level driven cultivation of business data resources has been neglected for decades. With the advent of information technology, Data were considered to be a technical matter, and business departments passed the responsibility for Data on to the IT department. As a result, business departments became alienated from the Data that they created themselves.

It's time for business departments to not only closely encounter with Data, but take ownership and responsibility to govern Data as assets... 

Stay tuned for my next post.

Sunday, April 27, 2014

How to Define the Target for Enterprise Information Management

In my recent post "The Organizational Challenge of Enterprise Information Management", I recommended to create a high-level conceptual data model as a target map for Enterprise Information Management (EIM), with Master Data Management (MDM) and Data Governance being core strategies to transform the organization from legacy structure to a data-driven business.

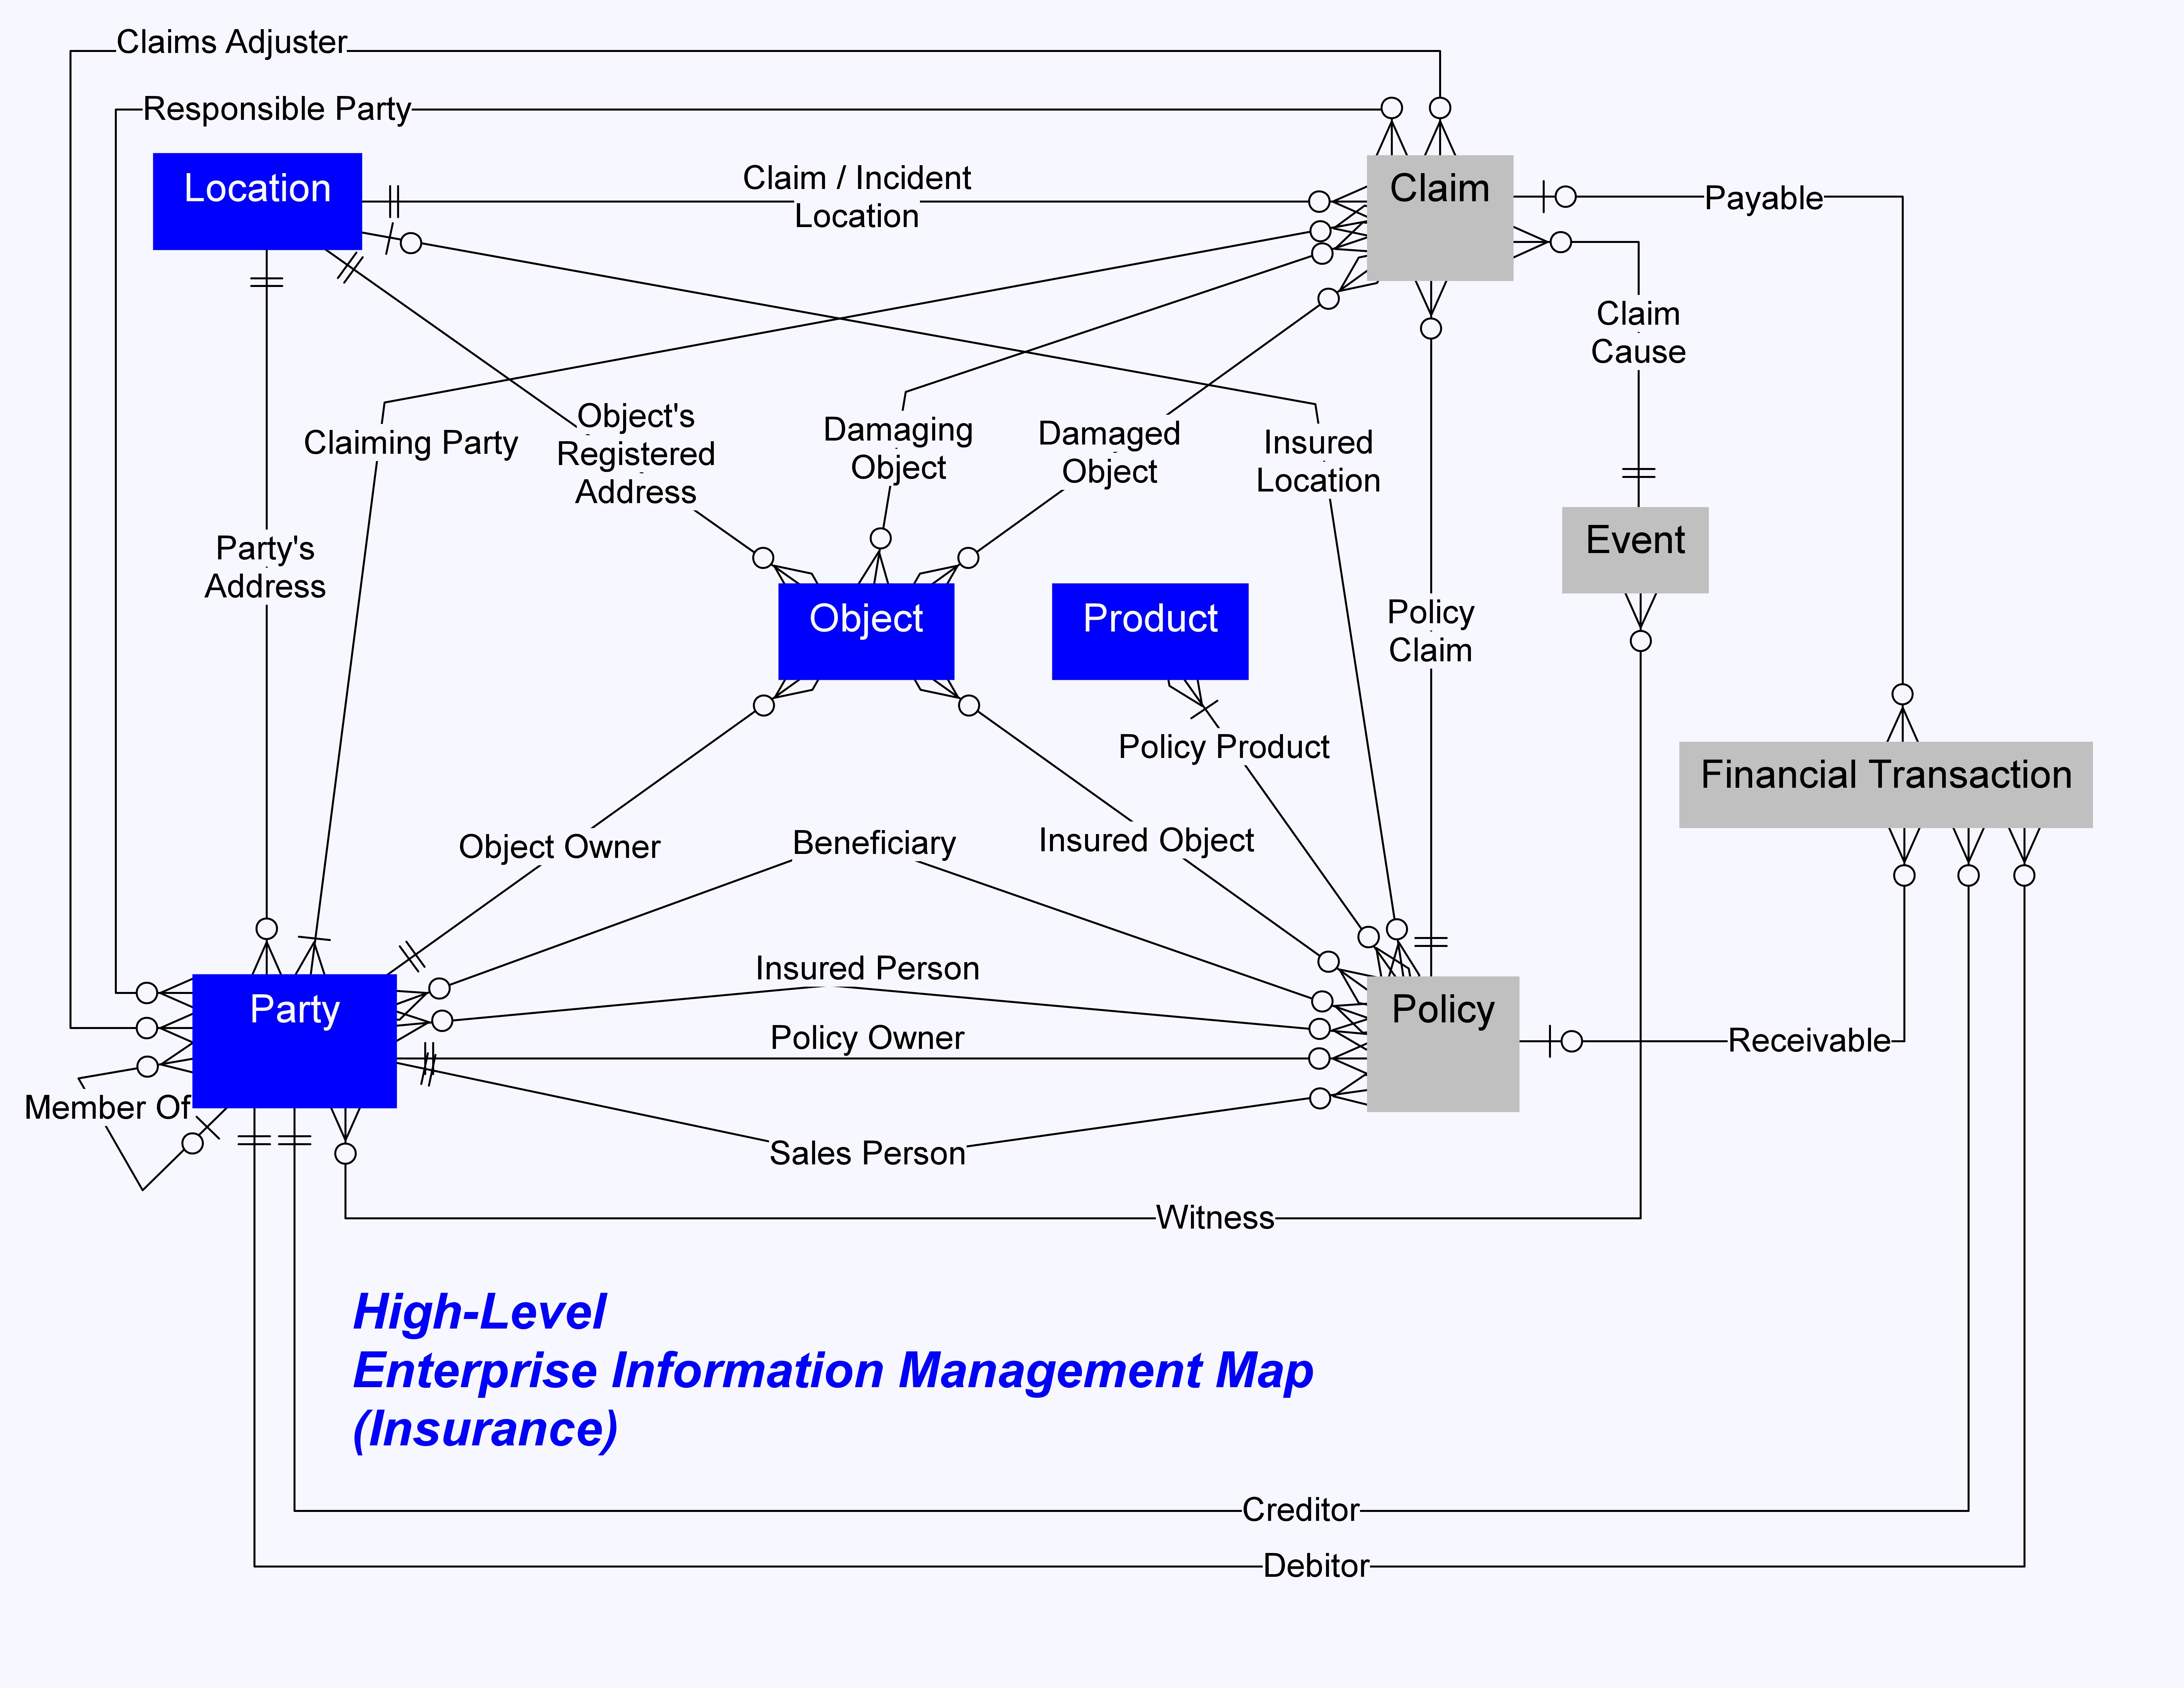
Below I have included a (not necessarily exhaustive) example of a high-level EIM map for an insurance company. 

Created with SILVERRUN RDM Relational Data Modeler - Tool for Conceptual, Logical and Physical Data Modeling
Click to enlarge

(The blue rectangles are Master Entities while the grey rectangles represent the major transactional entities.)

The decisive advantage of such an EIM map as a strategic orientation is: This target is not moving! As long as the business subject does not change (in this example: as long as the business does not add or drop any insured risk), this model does not need to be altered. It represents a sound structure that was valid 20 years ago (even if the term Master Data Management was not coined at that time), it is applicable today, and I dare to predict that it will still be in 20 years from now.

If applications are aligned to this model, they can answer business questions that a disparate system cannot (or cannot sufficiently), e.g. such as:
  • Which policies are owned by a certain party? (Single view of the customer)
  • Who are the most profitable / most risky customers? (Risk management)
  • Are there same groups of people that are - with changing roles - repeatedly involved in car accidents? (Fraud detection)
Being implementation-independent, a high-level EIM map will help any business in any industry to develop a long-term strategy to move from a siloed data / application architecture to integrated Enterprise Information Management and to provide answers to any organization's respective business questions.


Sunday, April 13, 2014

The Organizational Challenge of Enterprise Information Management

Medium and large enterprises as well as public administrations are constructed hierarchically, and that is for obvious reasons the best, if not the only principle to successfully conduct any endeavor that involves a certain number of people.

At some point in history, when the benefits of information technology were discovered, enterprises innocently imposed the same paradigm on their applications and also organized them by department. As a consequence, multiple information objects have been reinvented in several departments, and isolated data silos have been created, causing the known problems of conflicting definitions, redundancy and inconsistency that hinder to obtain complete customer views, to create real-time analytics as well as to swiftly respond to external legal and/or regulatory requirements. 

However, business information does not live in hierarchies but is represented by a network structure: the (conceptual) data model with master entities as their central objects.

Click to enlarge
Such a conceptual model on its highest levels serves as a target map for Enterprise Information Management (EIM) with Master Data Management (MDM) and Data Governance being core strategies to transform the organization from legacy structure to a data-driven business.

Since MDM and Data Governance demand harmonization throughout multiple departments, many organizations have set up committees to solve the related issues.

However, work for and participation in committees will always have to compete with departmental day-to-day tasks and therefore are in permanent risk of being treated as second priority. Also, EIM requires "central" tasks which do not have any "natural" representation in existing business units and therefore tend to end up in "IT" where they do not belong.

As a viable alternative, I suggest to replace the committee(s) by an additional permanent business unit that acts as the CEO's "right arm" to execute all central as well as coordinative tasks of EIM. For illustration purpose, I will here just name a few:
  • Develop and maintain the conceptual model that serves as the target for EIM
  • Define shared business entities e.g. Party (which then assumes its different roles such as Customer, Supplier, Employee in the operational business departments)
  • Develop strategies to accomplish legal and/or regulatory compliance 

In a future post, I will elaborate further on the role of the EIM unit, on necessary peer roles in the operational business departments and comment on frequently suggested responsibilities such as Chief Data Officer (CDO) and Data Stewards.

Thursday, October 10, 2013

A Different Introduction to Data Governance

Most likely, you have heard the term Data Governance before, or even read multiple attempts to define it...

No, Data Governance is not just a hype, and it's not the latest intrigue of your IT department. It's not about pushing responsibilities or blaming people. It's not about being picky, and you don't only do it to please others.  

It does not even require more work, actually it's the opposite, and - put in simple words - the principles of Governance can be summarized as: Do things right the first time!
 
And Data Governance: Do all things data right the first time!

Who wants to question this approach? What is the alternative? "Do it sloppily now, we'll fix it later if necessary!"? Well, if it's not necessary why even taking the time to do it sloppily? And if it's necessary, why spending additional time later when it's much easier (faster, more economical) to do it properly right away?

In any event, too many organizations have 'let it go' for too long, over time data issues have accumulated - and that's why we are talking Data Governance now...

Sunday, April 14, 2013

What is Data Governance?


Since Data Governance was introduced as a term, a variety of definitions has emerged which has caused contradictory interpretations and understanding of its meaning. Some people use Data Governance as a synonym for Data Quality, others believe it is something complementary. A third group considers Data Governance to be similar to Data Management...

Inspired by recent discussions, I like to offer the definition I refer to during my projects:
Data Governance is an organization's practice, based on documented policies and standards, to accomplish and maintain
  • Data Regulation Compliance
  • Data Strategy Compliance
  • Data Security
  • Data Quality
while applying the principles of Economy.
Data Regulation Compliance is the goal to comply with international and national laws and standards as well as with industry-specific regulatory requirements related to an organization's data.

Data Strategy Compliance is the goal to comply with (additional) data-related strategic and tactical directives which have been defined and issued by the organization's executive level and/or a line of business' management.

Data Security is the targeted degree of protecting the organization's data from corruption, theft, loss and unauthorized access.

Data Quality is the targeted degree of availability, provenance traceability, completeness, conformity, validity, correctness, consistency and timeliness of data that make it suitable for the organization's purpose of use.

Applying the principles of Economy means to accomplish and maintain the aforementioned targets with the highest possible return-on-investment (ROI), respectively, with the lowest cost (particularly considering the cost of inaction (COI)).
 
Please be invited to weigh in.