Saturday, October 14, 2017

Some Basic Recommendations for Data Quality

Inspired by the initiative of Prash Chandramohan (@mdmgeek) here, below please find some basic notes and recommendations for Data Quality.

1. Create a business data model while limiting its scope to data which
  • You are legally entitled to collect
  • Have a clear business purpose
  • Have a purpose that you can explain to the respective target group (customers, employees, suppliers etc.)
while avoiding to re-create entities / attributes that are rightfully already defined within the organization.

2. Define all business metadata regarding
  • Their (business) meaning
  • Format (length, data type)
  • Nullability
  • Range of values (where meaningful and possible).

3. Define use cases and related rules that serve a purpose-specific data quality.

4. As much as meaningful / possible: In business processes, programmatically
  • Enforce the rules for business data (quality)
  • At least, suggest a use-case-specific selection of values.

5. Educate business staff according to their role and responsibility in business processes about the purpose / use cases of data, in particular about the impact of
  • Their choice of values when creating or updating data
  • Deleting data.

6. Monitor the quality of data on a regular basis while applying / interpreting (use-case-specific) rules, e.g. using the Friday Afternoon Measurement (even if it's not Friday!).

7. Provide feedback to business staff and / or business analysts.


Sunday, August 20, 2017

GDPR & Personal Data - Context is Key and (Foreign) Key is Context

A logical data model is one of the important milestones on the road to GDPR (General Data Protection Regulation) compliance. Being the blueprint of an organization's semantic data and the relationships among them, the logical data model serves as the virtual hub between the existing physical data stores and the future implementation of a GDPR-compliant data architecture.

The logical data model even offers a GDPR-related bonus, as it teaches that being 'personal' (or non-'personal') is not an absolute characteristic of data, but depends on the context in which these data are made available.

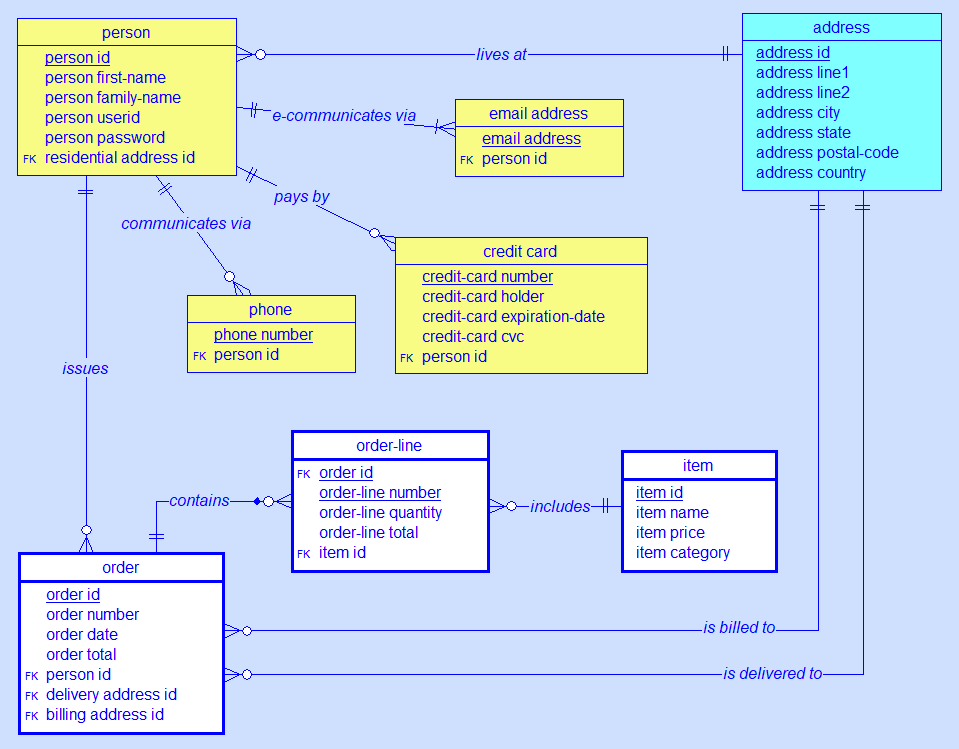
To illustrate the latter, let's look at an example of a logical data model which presumably represents the business of a B2C online retailer. This model may have been obtained as the result of the process described in my previous post "GDPR - How to Discover and Document Personal Data" or through any other modeling approach.

Click to enlarge

Which of these tables contain records with personal data?  As per the definition of 'personal data' imposed by the GDPR ('personal data' means any information relating to an identified or identifiable natural person), the answer is: All of them! 

Why? Because all tables are 'related' to the table 'person', i.e. there is a path from each table to 'person' (and vice versa).

This does not mean that all records of all tables shown here contain personal data, but those records that can be reached through a chain of foreign-key-value to primary-key-value links (or vice versa) from a 'person id' or to a 'person id'.

In other words, the existence of relationships (foreign keys) provides the context that categorizes records of data as 'personal' or 'non-personal'. For example, if we isolate the table 'address', its content simply constitutes a list of addresses which may exist in public reference databases such as Google Maps and therefore cannot be considered to contain personal data. But in the context shown in the above model, those records of the table 'address' that are identified by the value of the foreign key 'residential address id' in table 'person' (or by values of the foreign keys 'delivery address id' and 'billing address id' in table 'order') become personal data.

Still, the necessity and degree to protect personal data may vary from table to table and from column to column. The sensitivity of personal data must be evaluated, and the risk of processing personal data with respect to the rights and freedoms of natural persons must be assessed. Sensitivity and processing risk for each personal data element in isolation, but more importantly for their combination and in context will influence the physical design of data stores including measures of encrypting, pseudonymizing and anonymizing personal data to achieve GDPR compliance. But that will be subject to another post...

Wednesday, August 16, 2017

GDPR - How to Discover and Document Personal Data

One of the first steps for organizations on the journey to GDPR compliance is to find out what 'personal data' (i.e. any information relating to an identified or identifiable natural person) are stored where. For many organizations, this can be a tedious, cumbersome process, since very often the complete 'list' of all metadata describing personal data is not at hand right from the start. Making matters more complex, personal data's metadata (like any metadata) may be found under a variety of synonyms in different data stores. 

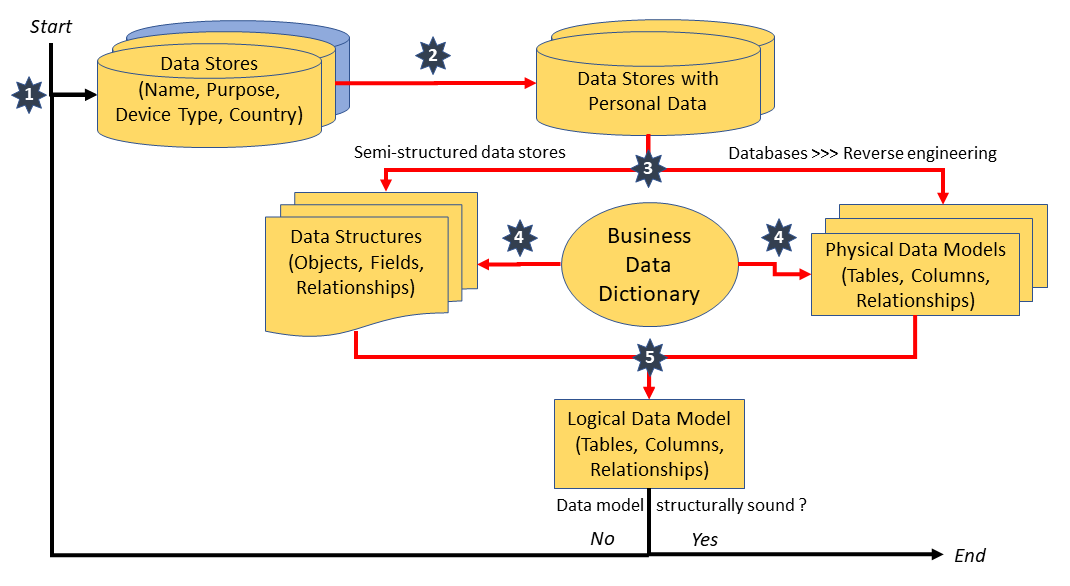
To streamline the process for data discovery as much as possible, I suggest a sequence of 5 steps which may need to be repeated several times. With each pass, additional personal data and/or their locations may be discovered based on the names of columns / fields added in a previous iteration. The process can be stopped once a consolidated, structurally sound logical data model has been obtained. 

Click to enlarge
The steps include:
  1. Create an inventory of all data stores. Record their name, purpose and  physical location (device type, country!). Important: Include locations where potential 'processors' (contractors) store business data on behalf of the 'controlling' organization! 
  2. Select (subset of) data stores that are already known to contain personal data. (In a first iteration, start searching data stores using typical metadata of personal data! In later iterations, search data stores using additional metadata of personal data based on the logical data model previously created (see step 5).) 
  3. Capture / reverse engineer the physical model of the selected data stores.
  4. For each selected data store, identify metadata (field names) of personal data and of objects relating to personal data. Assign business meaning to those fields by linking them to semantic items from your business data dictionary. (If you do not have a business data dictionary, create one in parallel by using existing documentation and involving subject matter experts!) 
  5. Create / enrich (partial) logical data model using the business data dictionary.
Although this is only the beginning of the journey, professional data (and process) modeling tools are obviously necessary on the road to GDPR compliance. (Note: All red arrows in the above image do not only indicate step sequence, but ought to also represent links among the related artifacts in the modeling tools' metadata repository.) Having already a business data dictionary in place and/or logical and physical data models tool-documented will greatly facilitate the process.

Stay tuned and read part 2 "GDPR & Personal Data - Context is Key and (Foreign) Key is Context" where I will demonstrate how context is important to determine whether data are to be considered personal or not with respect to the GDPR.

Sunday, June 4, 2017

GDPR Necessitates a Professional Data Modeling Tool

In his recent article Data governance initiatives get more reliant on data lineage info, David Loshin pointed out that "data lineage management offers a compelling scenario for improving the data governance process". Loshin distinguishes two aspects to Data Lineage, one structural and the other related to data flows which I characterize as follows:
  • Structural Data Lineage - mapping and tracking semantic data objects (and their synonyms) throughout the organization from elements of conceptual and logical schemas to their physical occurrences in databases
  • Dynamic Data Lineage - mapping and tracking the flow of semantic data objects (and their synonyms) from their sources, through the processes and data stores of the organization to downstream consumers.

In my post How The GDPR Can Propel An Organization's Informational Infrastructure I mentioned that recording Data Lineage is implicitly required by multiple regulations, most prominently the General Data Protection Regulation (GDPR).

Let's bring this to life using an example scenario of the not so distant future:

Thomas, an EU resident, is client of the online retailer xyzAnywhere Corp. which communicates with Thomas usually by email, but occasionally chooses to send him promotional letters by post mail. Thomas receives some of xyzAnywhere's promotional mail at his current residential address (as shown in his online profile), but also still some of their letters via mail forwarder as they are sent to his previous home. Thomas exercises his right granted by the GDPR to request a copy of the entire personal data that xyzAnywhere Corp. holds about him.

Upon receipt of that copy, Thomas realizes that the information provided to him does not include his previous residential address at all.

Regardless of how the communication between the customer and the organization may continue and leaving aside whether and how regulatory authorities will consider the case and penalize the organization, we can conclude that the organization failed to comply with GDPR (Art. 15), as it did not make the complete set of the customer's "personal data undergoing processing" available.

How could the organization have avoided to fail?

By employing a professional data modeling tool that especially
  • Features the creation of a business data dictionary where all semantic data objects can be uniquely named and well-defined for the entire organization
  • Supports to map and trace all synonym occurrences that may exist throughout the organization related to a data dictionary entry
  • Serves to represent a model of Master Entities and their physical distribution.

The data modeling tool SILVERRUN fully supports the above criteria and helps you to build a solid foundation for Data Model Management, Master Data Management and Data Governance.
 
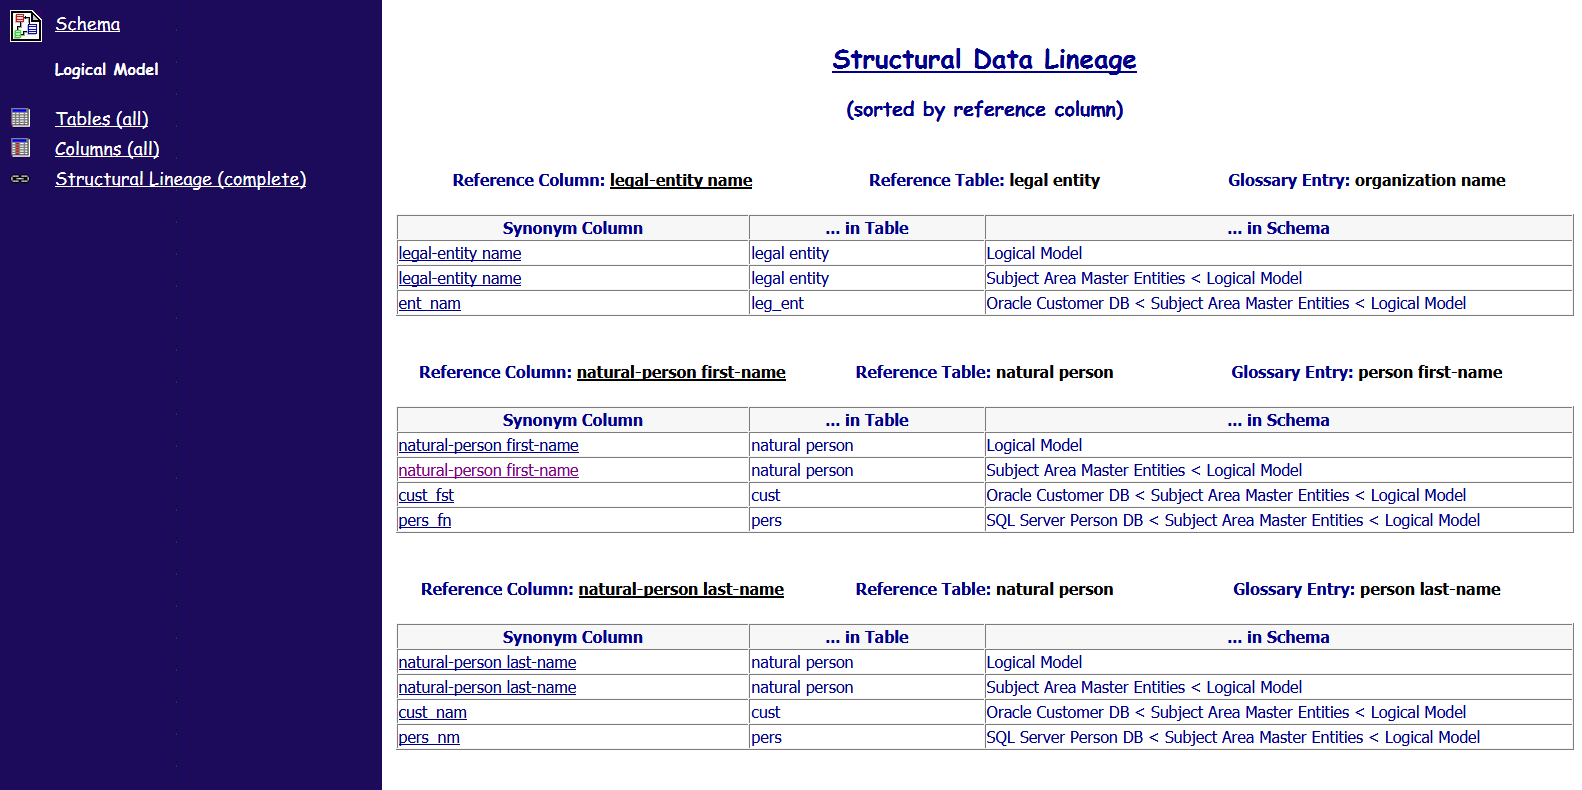
Below please see how SILVERRUN reports Structural Data Lineage which would have helped in the above example scenario to identify all database columns that constitute synonyms e.g. of the data dictionary item "person last-name" and thus define the data model needed to systematically extract all personal data related to a particular customer.
 
SILVERRUN RDM Relational Data Modeler - Tool for Conceptual, Logical and Physical Data Modeling
Click to enlarge


To be clear:  Links between a data dictionary item (glossary entry) and its synonyms can only be created by "brainware", not by software (alone) since the semantics behind any data object has to be understood first. However, with human guidance, SILVERRUN can integrate the puzzle pieces that may be available through reverse engineering of databases, importing spreadsheets, reusing existing models and accessing other sources of documentation. 

Once integrated, the resulting data model constitutes the solid ground to build a future-proof Master Data Management system and to flexibly respond to regulatory requirements as e.g. stipulated by the GDPR.

[In the spirit of full disclosure: I represent Grandite, the supplier of the SILVERRUN tools for data and process modeling.]

Monday, April 3, 2017

GDPR - More Than Just Another Regulation

It has become all too common that business initiatives targeting infrastructural improvements such as Enterprise Architecture & Business Modeling, Data Governance & Master Data Management, Privacy & Data Protection are put on the back-burner or are totally suppressed in favor of endeavors that promise monetary benefits in the short term.

Accordingly, few organizations are really prepared for a timely response to requirements imposed by law or by industry-specific regulatory authorities. Considering the usually moderate fines for non-compliance and potentially little other consequences, delayed reaction and acceptance of the risk to eventually be hit by the proverbial stick have become an element of business calculation.

When conceiving the General Data Protection Regulation (GDPR), the European Union (EU) obviously anticipated that a non-negligible number of organizations would be reluctant to comply rather than making reasonable efforts. EU lawmakers have therefore replaced the penalty stick with a sledgehammer right out of the gate (May 2018). In plain English, the EU's powerful message says: 

"If you, the organizations of the world, process personal data of our people, you have to respect the provisions of the GDPR, otherwise we will hold you accountable with fines of up to EUR 20 million, while in return we apply the same rules to our organizations when it comes to processing personal data of your people."

Not emphasizing nations or ideologies, but simply putting people first, is not only a strong political statement, but a directive that will change the way how business will be done in the foreseeable future. It is a contemporary way of saying "the customer is king" while forcing organizations to prioritize the long-due overhaul of their informational infrastructure. 

Too bad that we need lawmakers to remind us of what should have been common sense in the first place.